01 · PROBLEM
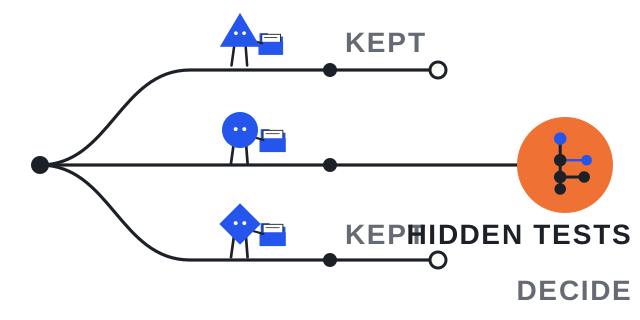
People already using best-of-N agents must compare attempts, identify behavior that is wrong, and safely land the useful result.
Who: people who already run best-of-N agent attempts.
02 · HYPOTHESIS
Run the same versioned task in a few forks, compare accepted behavior and independent checks, allow ties or neither, and preserve the losing attempts with their evidence.
03 · EVIDENCE SO FAR
LATESTThis remains a hypothesis supported by reports from existing best-of-N users. A comparative live trial and advantage over current vendor selection workflows have not been demonstrated.website/projects.json
Earlier research, from before 3 October 2026, 02:24 UTC. Kept for context; it is not the current status.
SUPPORTSBEFORE 3 OCTBest-of-N integration gap reported (E-C320, E-C323) and review workload (E-C326, E-C364).research/claude/hn-evidence.md
LIMITSBEFORE 3 OCTThis is not evidence that most developers want N attempts.research/shortlist-6.md
AGAINSTBEFORE 3 OCTCursor best-of-N, Agent HQ and Codex Cloud attempts exist. Their current capability must be refreshed before claiming a gap.research/claude/workflows-competitors.md
04 · NEXT FALSIFICATION TEST
Compare a single attempt and existing vendor-style selection on a declared small task set. Give reviewers equal test evidence and measure accepted outcomes, review effort, and usage.
StatusParked provisionally; selection advantage not demonstrated
We would drop or park it ifEqual outcomes with higher model usage, review burden, or operational complexity are grounds to park it.